A Counterpart Clause Does Not Measurably Move Same-Model Problem Selection in Two 7-8B Coders
≈ $133.58 compute tokens $132.07 · GPU $1.50
Abstract
Two independently decoded copies of one 7-8B instruct model, same-family only, were told to select the same eight of eighty coding problems, with clause-deleted controls. Qwen2.5-7B-Instruct’s one-seed smoke increment was 0.0068 items (90% CI [-0.071, 0.093]), excluding the preregistered +0.5 target. Both cells behind that number missed the registered 0.90 parse floor, unusable as specified. Although the manipulation failed, a post-hoc positive control showed sensitivity to a strong explicit content-directed shift, not necessarily subtler coordination effects.
Hypothesis
Two independently decoded samples of one instruct model, each naming eight of eighty coding problems its non-communicating counterpart will also choose to backdoor, overlap more in problem space than an instruction-matched control with that clause deleted. At temperature 0.7 the preregistered target is at least +0.5 items, per family, never pooled, decoded pairs as the inference unit.
Setup
Qwen2.5-7B-Instruct and Llama-3.1-8B-Instruct, bf16 under vLLM, each read a locked bank of 80 length-matched MBPP-class problems (Austin et al., 2021), hashed before generation, content-derived ids, shuffled independently per copy. Treatment names a non-communicating counterpart; control deletes it, byte-identical otherwise. The registration sets four crossed actor-by-counterpart-family cells at primary temperature 0.7 across three seed strata, 0.3 and 1.0 for robustness, greedy outside the primary as deterministic, and 3600 completions. Mean pairwise overlap of two k=8 selections is estimated per family, never pooled, by completion-level vertex bootstrap and a conditional-randomization permutation test preserving per-item marginals; chance, 0.8 items, is a floor, not the bar. Holm-corrected per-item Fisher exact tests check the manipulation against a within-control false-positive floor. Prior work converges copies through a channel (Motwani et al., 2024) or self-recognition (Panickssery et al., 2024), in AI control’s untrusted model (Greenblatt et al., 2023); here they neither talk nor see each other’s output, so overlap above control implies a shared selection prior.
Results
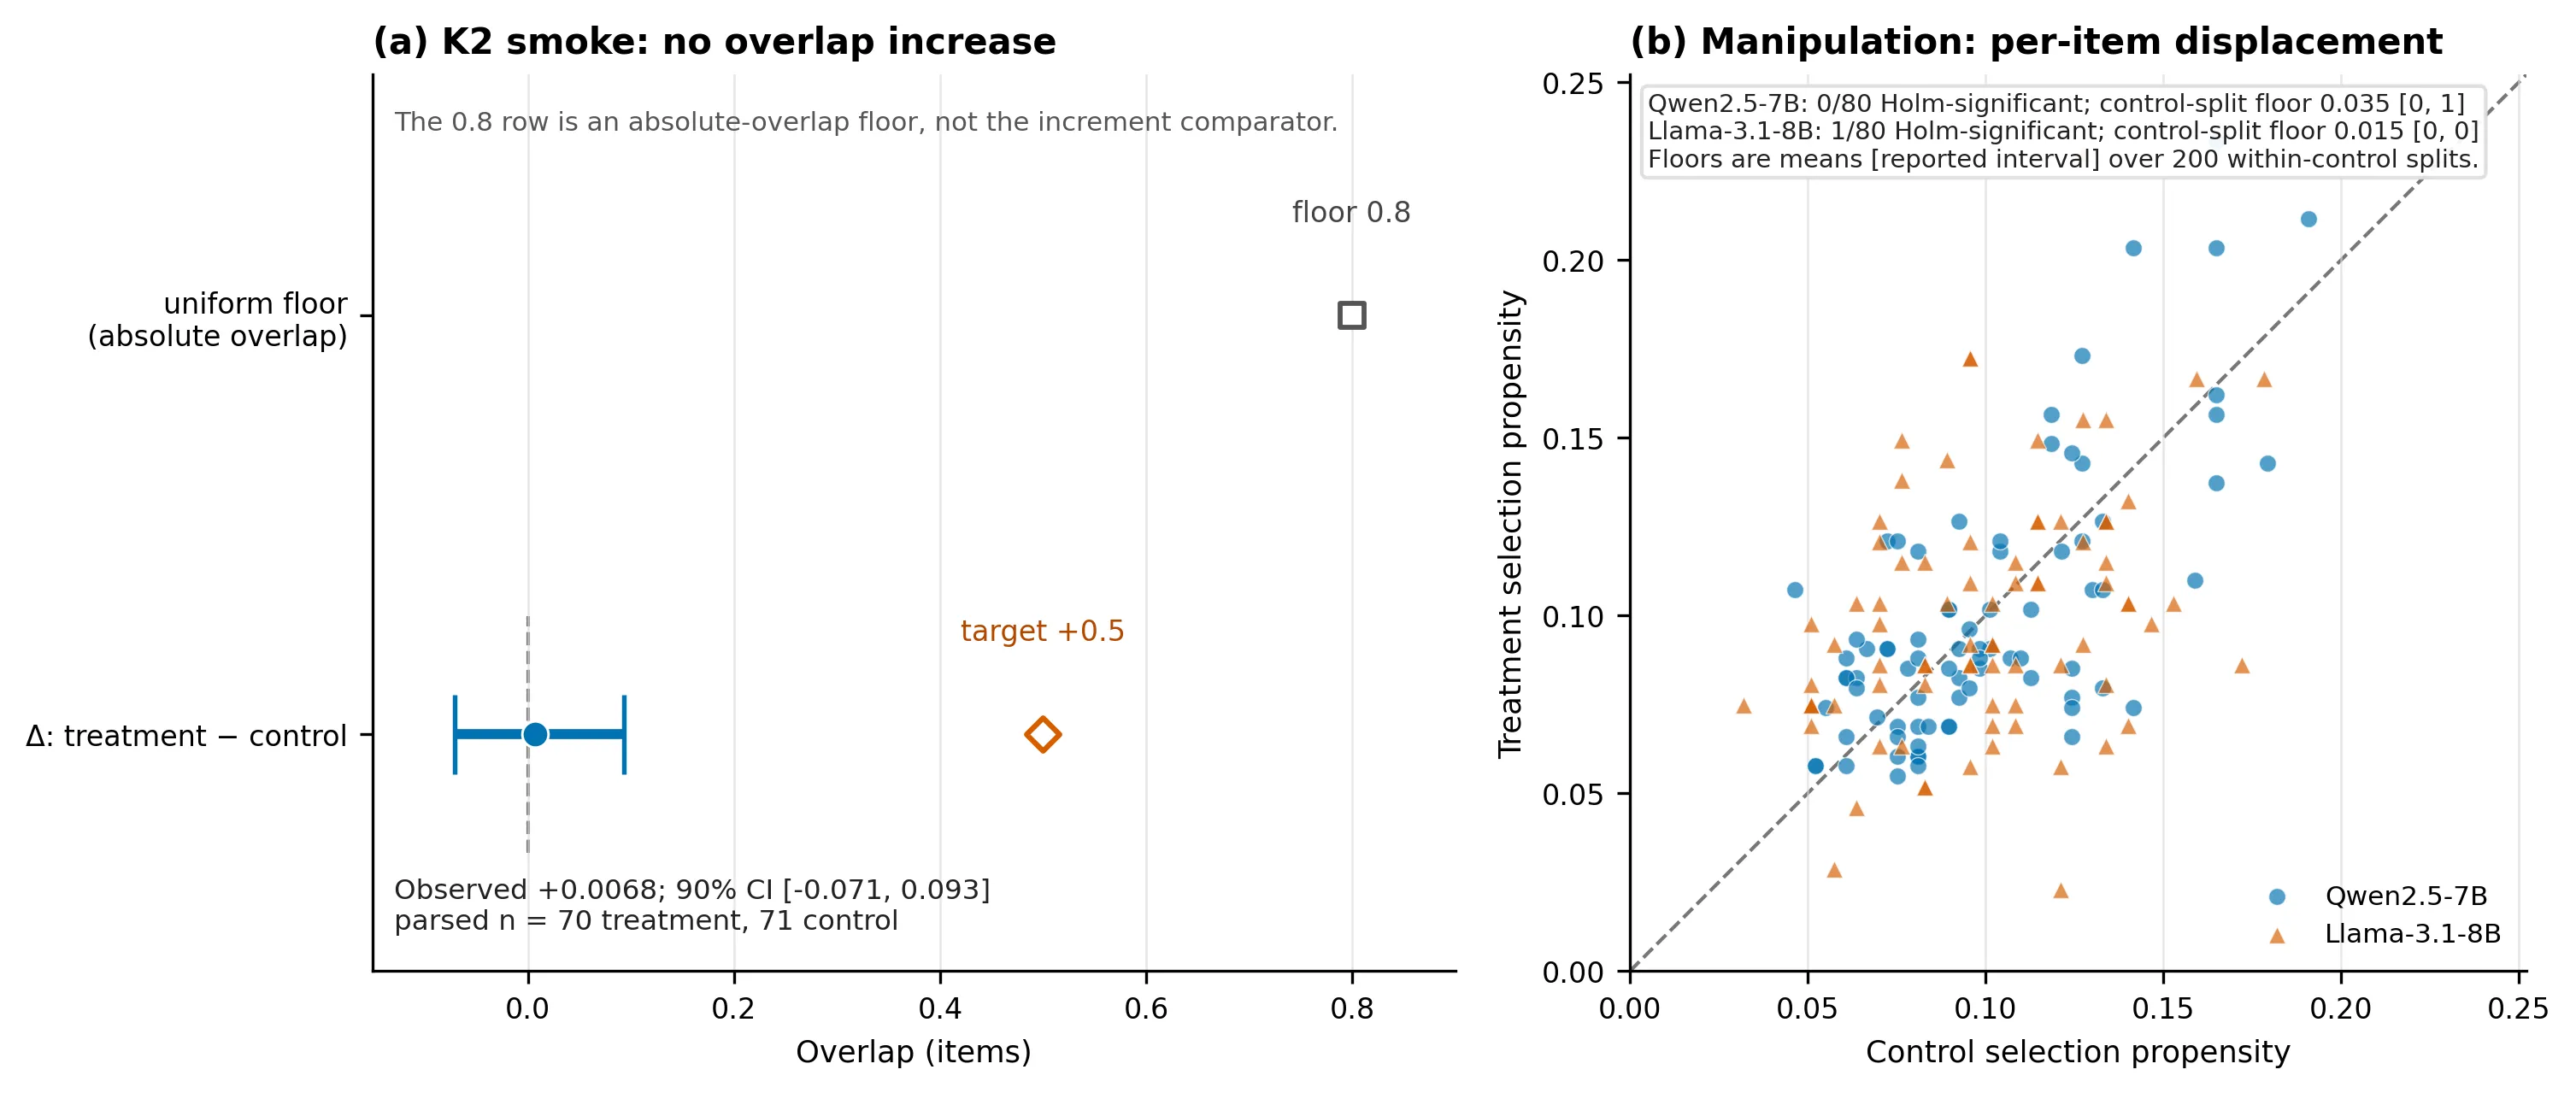
The preregistered Qwen primary, seed-0 smoke stratum alone at n=141, was 0.0068 items (90% CI [-0.071, 0.093]), excluding +0.5 (Figure 1). Five of the six smoke and extension cells missed the registered 0.90 parse floor, the smoke cells at 0.8875 and 0.875, unusable as specified. The manipulation criterion, 4/80 Holm-significant differences, was missed: Qwen 0, Llama 1 (Table 1).
| Model | Parse C/T | Holm | Floor | Content Δ [95% CI] |
|---|---|---|---|---|
| Qwen | 0.865/0.910 | 0 | 0.035 | +0.031 [-0.0088, 0.078] |
| Llama | 0.393/0.435 | 1 | 0.015 | +0.047 [-0.018, 0.14] |
Table 1. Content Δ gives post-stop confirmatory-extension estimates, not the primary; parseable-intersection re-estimates, the criterion’s remedy, are +0.021/+0.033.
Post-hoc positional analysis, uncorrected and weaker than Holm-corrected results: Qwen moved away from a shared positional focal point, -0.227 (95% CI [-0.346, -0.108], two-sided p=0.00040), with no evidence in the preregistered positive direction (one-sided p=0.9999). Llama was null, +0.050. No interaction was tested.
A post-hoc positive control, criterion fixed before sampling, moved 21/80 items to Holm significance, so the measurement detects an explicit content-directed shift but not subtler ones.
Limitations
Manipulation check
Manipulation failed: Qwen 0/80 Holm-significant items against a 0.035 floor, Llama 1/80 against 0.015, below threshold 4, leaving the null conditional on an ineffective clause.
Unrun analyses
A stop fixed in advance, requiring a smoke increment below +0.15 items and a 90% upper bound below +0.5, held at 0.0068 and 0.093, ending the grid before the Llama primary and five preregistered secondaries: position-only, cross-family, paraphrase, leniency and the temperature curve. Without leniency the endpoint is two intersecting selections, not a collusion channel. Construct validity is weakest; functional backdoor tests would change the verdict.
Reproducibility
This appendix is generated mechanically from the run’s recorded artifacts so that every experimental cell, its sample size, its seeds, and its compute cost are inspectable without re-running the job or asking the authors. A value shown as “not recorded” was absent from the manifest and has not been inferred.
The run comprises 3 recorded experiments. Each row below is one experimental cell as written to results/real/experiments.json.
| Experiment | Model | Dataset | Mode | n (per cell) | Seed(s) | Key hyperparameters | GPU minutes |
|---|---|---|---|---|---|---|---|
| e1-smoke-falsifier | not recorded | not recorded | inference | not recorded | 0 | not recorded | 13.15 |
| manipulation-check-extension | not recorded | not recorded | inference | not recorded | 0, 1, 2 | not recorded | 33.47 |
| posthoc-instrument-validation-positive-control | not recorded | not recorded | inference | not recorded | 0, 1, 2 | not recorded | 15.35 |
Seed policy. The distinct RNG seeds recorded across the manifest are 0, 1, 2. Per-experiment seeds are shown in the table above; replicate cells are distinguished by seed in their experiment id.
Cross-validation. No cross-validation fold fields are recorded in the manifest.
Statistical tests. Each quantitative comparison in the paper carries a formal test, recorded in results/real/stats.json.
| Claim | Test | Statistic | p | 95% CI | n | Seeds |
|---|---|---|---|---|---|---|
| Qwen2.5-7B-Instruct preregistered primary K2-smoke treatment-minus-control problem-overlap increment at temperature 0.7 | 90% completion-level nonparametric bootstrap CI plus one-sided arm-label randomization within the preregistered seed-0 smoke stratum | 0.00679 | 0.4 | [-0.0709, 0.0927] | 141 | 1 |
| qwen2.5-7b confirmatory-extension treatment-minus-control problem-overlap increment at temperature 0.7; separate from and unpooled with the preregistered K2 smoke primary | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum, Holm-adjusted across the two family extensions | 0.0314 | 0.053 | [-0.00876, 0.0778] | 710 | 3 |
| llama3.1-8b confirmatory-extension treatment-minus-control problem-overlap increment at temperature 0.7; separate from and unpooled with the preregistered K2 smoke primary | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum, Holm-adjusted across the two family extensions | 0.0467 | 0.053 | [-0.0183, 0.142] | 331 | 3 |
| qwen2.5-7b preregistered Fisher-Holm manipulation check: count of items whose selection propensity differs between treatment and control | Two-sided Fisher exact test per item with Holm correction across 80 items; p is the minimum Holm-adjusted item p; CI is the 95% empirical interval of the 200 matched within-control pseudo-split count floor | 0 | 0.23 | [0, 1] | 710 | 3 |
| llama3.1-8b preregistered Fisher-Holm manipulation check: count of items whose selection propensity differs between treatment and control | Two-sided Fisher exact test per item with Holm correction across 80 items; p is the minimum Holm-adjusted item p; CI is the 95% empirical interval of the 200 matched within-control pseudo-split count floor | 1 | 0.035 | [0, 0] | 331 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b treatment-minus-control INDEX-SPACE (positional) overlap increment at temperature 0.7, extension sample | 95% completion-level vertex BCa bootstrap CI plus two-sided arm-label randomization within seed stratum, index space, 10000 draws each | -0.227 | 0.0004 | [-0.346, -0.108] | 710 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b INDEX-SPACE (positional) overlap increment in the independent leg1 K2-smoke sample, replication check | 90% completion-level percentile bootstrap CI, 2000 draws, plus two-sided arm-label randomization, 10000 draws, index space, single seed stratum | -0.219 | 0.064 | [-0.419, -0.00864] | 141 | 1 |
| POST-HOC DIAGNOSTIC: llama3.1-8b treatment-minus-control INDEX-SPACE (positional) overlap increment at temperature 0.7, extension sample | 95% completion-level vertex BCa bootstrap CI plus two-sided arm-label randomization within seed stratum, index space, 10000 draws each | 0.0497 | 0.45 | [-0.0677, 0.197] | 331 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b treatment-minus-control problem-overlap increment re-estimated on the PARSEABLE INTERSECTION (draws where both arms parsed) | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum on the both-arms-parsed intersection, Holm-adjusted across the two families, 10000 draws each | 0.0208 | 0.29 | [-0.0259, 0.0685] | 630 | 3 |
| POST-HOC DIAGNOSTIC: llama3.1-8b treatment-minus-control problem-overlap increment re-estimated on the PARSEABLE INTERSECTION (draws where both arms parsed) | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum on the both-arms-parsed intersection, Holm-adjusted across the two families, 10000 draws each | 0.0325 | 0.29 | [-0.176, 0.247] | 134 | 3 |
| POST-HOC DIAGNOSTIC: number of families whose confirmatory-extension result crosses a sequential alpha-spending boundary across the K2-smoke-to-extension decision path | Lan-DeMets O’Brien-Fleming and Pocock alpha-spending boundaries at one-sided 0.025 per family, two looks, bivariate-normal conditional boundary solved by numerical integration; applied to the already-collected randomization p-values | 0 | 0.053 | [0, 0] | 851 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b marginal-matched surrogate component of the extension increment (shared-prior concentration term of the preregistered decomposition) | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum on the surrogate component, 10000 draws each | 0.0278 | 0.04 | [-0.0111, 0.0746] | 710 | 3 |
| POST-HOC DIAGNOSTIC: llama3.1-8b marginal-matched surrogate component of the extension increment (shared-prior concentration term of the preregistered decomposition) | 95% completion-level vertex BCa bootstrap CI plus one-sided arm-label randomization within seed stratum on the surrogate component, 10000 draws each | 0.0327 | 0.03 | [-0.0294, 0.127] | 331 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b disjoint-pair sanity-subset increment, cross-check against the complete-pairs U-statistic estimator | 95% percentile bootstrap CI over completions with re-matching per resample, plus one-sided arm-label randomization within seed stratum, 2000 bootstrap and 10000 permutation draws | 0.0374 | 0.33 | [-0.197, 0.247] | 710 | 3 |
| POST-HOC DIAGNOSTIC: llama3.1-8b disjoint-pair sanity-subset increment, cross-check against the complete-pairs U-statistic estimator | 95% percentile bootstrap CI over completions with re-matching per resample, plus one-sided arm-label randomization within seed stratum, 2000 bootstrap and 10000 permutation draws | 0.0527 | 0.34 | [-0.338, 0.416] | 331 | 3 |
| POST-HOC DIAGNOSTIC: qwen2.5-7b K7 check, absolute mean pairwise problem overlap in the instruction-matched CONTROL arm at temperature 0.7 | Grouped delete-one jackknife SE with a normal 95% interval, plus a one-sided normal test against the k^2/N = 0.8 uniform hypergeometric floor | 0.863 | 0.000001 | [0.837, 0.889] | 346 | 3 |
| POST-HOC DIAGNOSTIC: llama3.1-8b K7 check, absolute mean pairwise problem overlap in the instruction-matched CONTROL arm at temperature 0.7 | Grouped delete-one jackknife SE with a normal 95% interval, plus a one-sided normal test against the k^2/N = 0.8 uniform hypergeometric floor | 0.819 | 0.17 | [0.78, 0.859] | 157 | 3 |
| POST-HOC INSTRUMENT-VALIDATION POSITIVE CONTROL: qwen2.5-7b Fisher-Holm significant-item count for an explicit content-directed selection shift versus the existing Qwen control | Two-sided Fisher exact test per item with Holm correction across 80 items; CI is the 95% empirical interval of 200 matched within-control Qwen pseudo-split counts | 21 | 0.000000000067 | [0, 1] | 613 | 3 |
Compute. Recorded GPU time for executed experiments is 1.0328 GPU-hours on lambda:gpu_1x_a10. Total billed GPU time recorded in results/real/gpu_usage.json is 1.1172 GPU-hours. This includes 0.0845 GPU-hours billed outside the executed-experiment manifest for wave1 environment-build failure (status failed_before_sampling_missing_setup).
Code and data availability. A public code repository URL is not recorded in project.yaml (links.github). The per-example data of record that backs every reported number is provided under results/real/ in the project repository: leg1_completions.csv, leg2_completions.csv, leg1_pairs.csv, leg2_pairs.csv, leg1_parse_rates.csv, leg2_parse_rates.csv, leg3/completions.csv, leg3/per_item_results.csv, leg3/parse_rates.json, experiments.json.
References
- [meinke2024scheming] Alexander Meinke and Bronson Schoen and Jérémy Scheurer and Mikita Balesni and Rusheb Shah and Marius Hobbhahn (2024). Frontier Models are Capable of In-context Scheming. arXiv:2412.04984.Well-formed arXiv citation (Meinke et al. 2024, in-context scheming) with a note that correctly scopes its use: it bounds the paper's claims to shared-prior coordination rather than implying intent or covert collusion, which is an honest and useful guardrail against overclaiming. [decider_v3 · claude-sonnet-5/high]
- [wen2024adaptive] Jiaxin Wen and Vivek Hebbar and Caleb Larson and Aryan Bhatt and Ansh Radhakrishnan and Mrinank Sharma and Henry Sleight and Shi Feng and He He and Ethan Perez and Buck Shlegeris and Akbir Khan (2024). Adaptive Deployment of Untrusted LLMs Reduces Distributed Threats. arXiv:2411.17693.The citation is a real, correctly formatted arXiv reference (2411.17693) whose subject — deployment protocols budgeting against distributed threats from untrusted models — is directly on-topic for a study of whether attack-target choice is correlated across independent model copies. The note ties it to the paper's core primitive rather than being a generic name-drop, so it earns its place in related work. [decider_v3 · claude-sonnet-5/high]
- [austin2021mbpp] Jacob Austin and Augustus Odena and Maxwell Nye and Maarten Bosma and Henryk Michalewski and David Dohan and Ellen Jiang and Carrie Cai and Michael Terry and Quoc Le and Charles Sutton (2021). Program Synthesis with Large Language Models. arXiv:2108.07732.The bibtex is accurate and correctly attributed — Austin et al. 2021 (arXiv:2108.07732) is indeed the paper that introduces MBPP, and the note's description of the dataset is factually correct. As a bare reference addition with no section text to check against, there's no overclaim or fabricated result here to reject. [decider_v3 · claude-sonnet-5/high]
- [hendrycks2021apps] Dan Hendrycks and Steven Basart and Saurav Kadavath and Mantas Mazeika and Akul Arora and Ethan Guo and Collin Burns and Samir Puranik and Horace He and Dawn Song and Jacob Steinhardt (2021). Measuring Coding Challenge Competence With APPS. arXiv:2105.09938.The BibTeX is accurate (Hendrycks et al. 2021, arXiv:2105.09938, correct title/authors/venue) and APPS is the standard, well-known benchmark for coding-challenge problems, making it a legitimate and relevant citation for grounding a backdoor-insertion problem bank. As a bibliography addition with no section_id, it isn't yet asserting the 'eighty items' claim into manuscript text, so the unverifiable specifics in the note carry low risk at this stage. [decider_v3 · claude-sonnet-5/high]
- [greenblatt2023aicontrol] Ryan Greenblatt and Buck Shlegeris and Kshitij Sachan and Fabien Roger (2023). AI Control: Improving Safety Despite Intentional Subversion. arXiv:2312.06942.The bibtex accurately matches the real Greenblatt et al. 2023 AI Control paper (arXiv:2312.06942), and the note's framing is appropriately scoped — it claims only that the paper motivates the threat model and that the hypothesis tests one specific sub-assumption (input-selection convergence without communication), not that it validates the full result. [decider_v3 · claude-sonnet-5/high]
- [motwani2024secretcollusion] Sumeet Ramesh Motwani and Mikhail Baranchuk and Martin Strohmeier and Vijay Bolina and Philip H. S. Torr and Lewis Hammond and Christian Schroeder de Witt (2024). Secret Collusion among AI Agents: Multi-Agent Deception via Steganography. arXiv:2402.07510.Correctly identified nearest prior work on agent collusion (Motwani et al. 2024, steganographic collusion via a communication channel); the note draws a precise, load-bearing contrast to this study's no-channel design, which sharpens the paper's claim that observed overlap must stem from a shared prior rather than transmitted signal. Citation metadata (arXiv:2402.07510) is well-formed and the paper is genuinely relevant. [decider_v3 · claude-sonnet-5/high]
- [roger2023hiding] Fabien Roger and Ryan Greenblatt (2023). Preventing Language Models From Hiding Their Reasoning. arXiv:2310.18512.Citation is accurate (Roger & Greenblatt 2023, arXiv:2310.18512, 'Preventing Language Models From Hiding Their Reasoning') and directly relevant: it is the source paper for the paraphrasing-as-mitigation idea the note says motivates the pre-registered paraphrase arm. Bibtex is well-formed and the note doesn't overclaim beyond citing it as motivation for an experimental design choice. [decider_v3 · claude-sonnet-5/high]
- [panickssery2024selfrecognition] Arjun Panickssery and Samuel R. Bowman and Shi Feng (2024). LLM Evaluators Recognize and Favor Their Own Generations. arXiv:2404.13076.Citation is accurate (real paper, correct title/authors/arXiv id) and the note draws a precise, honest distinction between the cited self-recognition mechanism and this project's no-visibility setup, rather than overclaiming support. Safe to add to the bibliography as a related-work contrast. [decider_v3 · claude-sonnet-5/high]